Introduction
Speed defines modern digital commerce, yet engineering teams routinely stumble over fragile architectures and manual release bottlenecks. Development leaders actively search for proven, battle-tested operational strategies that accelerate delivery velocity while safeguarding production uptime.
Bridging the operational divide demands unified team accountability and automated pipeline controls. When organizations replace manual deployment chores with standardized self-service tools, developers focus entirely on building high-value customer features. This comprehensive blueprint details actionable frameworks, platform design patterns, and reliability principles that transform traditional IT setups into resilient, high-velocity software engines.
What Does DevOps Actually Help a Business Do?
DevOps breaks down the institutional wall that historically separated software coders from IT operations personnel. By instituting shared accountability across the entire deployment lifecycle, developers and systems engineers solve production anomalies collaboratively. This shared ownership model prevents operational friction and eliminates costly release delays.
At the same time, teams construct automated delivery pipelines that replace error-prone manual server changes. Developers commit source code, automated suites run unit tests immediately, and delivery engines roll out verified artifacts to target environments. Consequently, enterprises replace stressful quarterly release cycles with safe, routine daily updates.
Why Are So Many Businesses Moving Toward DevOps?
Modern customers expect constant digital feature enhancements paired with unbroken service reliability. Organizations that rely on manual configurations consistently lose competitive ground to agile firms that ship code several times a day. Field research confirms that elite engineering departments deploy changes hundreds of times faster while recovering from outages in minutes rather than days.
Furthermore, end-to-end pipeline automation shields engineers from burnout and repetitive toil. Technical staff dedicate their problem-solving talents to high-impact product architecture instead of troubleshooting midnight deployment outages. Therefore, companies boost team morale, attract elite technical talent, and accelerate their product roadmaps.
Where Can DevOps Consulting Make a Difference?
Executing large-scale operational modernizations demands deep domain mastery that internal teams often lack. Specialized DevOps Consulting Services supply rigorous architectural assessments, targeted optimization roadmaps, and custom pipeline overhauls. Independent advisors detect delivery bottlenecks rapidly because they analyze diverse infrastructure topologies across multiple enterprise sectors.
| Optimization Layer | Core Strategic Focus | High-Impact Deliverable | Target Organization |
|---|---|---|---|
| Operational Audit | Pipeline Bottleneck Discovery | Actionable Modernization Blueprint | Companies launching digital transformations |
| Continuous Delivery | Release Automation & Testing | Production-Ready CI/CD Workflows | Teams struggling with manual release steps |
| Declarative Platform | Infrastructure as Code (IaC) | Reusable Terraform Blueprints | Enterprises modernizing legacy data centers |
Enlisting external engineering guidance protects businesses from costly architecture missteps during early transition phases. Experienced specialists help leaders choose sustainable tooling, enforce automated compliance checks, and upskill internal staff, ensuring operational maturity advances smoothly.
What Are Managed DevOps Services and Who Needs Them?
Growing organizations frequently lack the budget or administrative capacity to maintain an around-the-clock internal operations center. Under these conditions, Managed DevOps Services supply continuous infrastructure maintenance, system patching, and continuous deployment supervision. This hands-on operational model safeguards production environments without pulling feature developers away from core product roadmaps.
Similarly, expanding mid-market companies secure massive technical leverage through managed operational partnerships. Instead of spending quarters hunting for hard-to-find infrastructure specialists, leadership engages a fully formed engineering unit on day one. These dedicated engineers monitor system health, resolve critical infrastructure alerts, and optimize cloud consumption around the clock.
How Does Cloud Computing Change the Way Teams Build Software?
Traditional on-premise infrastructure requires substantial upfront capital outlays and months of hardware procurement. Cloud computing changes this equation by providing elastic virtual machines, managed storage, and automated network controls on demand. Developers spin up production-ready environments in minutes using declarative code rather than waiting for physical hardware shipments.
Furthermore, cloud vendors offer managed database, messaging, and networking layers that eliminate low-level server administration. Engineering teams stop managing operating system kernels and start architecting decoupled, distributed services that scale automatically during high-volume customer surges.
When Should You Consider Cloud Consulting Services?
Architecting secure, fault-tolerant infrastructure across distributed cloud ecosystems demands specialized engineering experience. Engaging seasoned Cloud Consulting Services guarantees that your architects design resilient, compliant, and cost-effective environments across AWS, Microsoft Azure, or Google Cloud Platform.
Moreover, cloud consultants institute programmatic guardrails that curb runaway infrastructure expenses. Experienced advisors analyze telemetry records, enforce auto-scaling rules, and configure real-time budget alarms, ensuring cloud spending directly mirrors business expansion.
What Should You Know Before Moving Applications to the Cloud?
Migrating complex systems without a structured assessment plan leads to operational sprawl and uncontrolled server billing. Engineering leaders must evaluate and categorize legacy portfolios systematically before shifting production workloads into public cloud networks.
- Rehost: Moves virtual machine workloads straight into cloud compute layers without rewriting business logic, facilitating rapid data center closures.
- Replatform: Upgrades supporting platform services, such as adopting cloud-managed databases, while keeping primary code intact.
- Refactor: Re-architects monolithic codebases into containerized microservices to maximize cloud-native scalability and fault tolerance.
- Retire or Retain: Decommissions obsolete applications or maintains deeply coupled legacy systems on-premise until future modernization cycles.
Deploying proven Cloud Migration Services guarantees minimal application downtime, protects data integrity throughout transfers, and safeguards business continuity across production workloads.
Why Is Kubernetes Becoming Important for Modern Applications?
Containers package software code alongside runtime libraries, ensuring identical execution across developer workstations, staging clusters, and production servers. However, coordinating hundreds of interconnected containers across extensive server fleets creates massive administrative friction.
Kubernetes solves this operational challenge by automating container scheduling, horizontal scaling, self-healing restarts, and service discovery. When an application container crashes, Kubernetes detects the failure and relaunches the workload instantly. When user traffic spikes, the orchestrator adds container replicas within seconds to preserve system response times.
When Can Kubernetes Consulting Services Be Useful?
Managing Kubernetes reliably inside production environments requires deep systems administration skills. In-house teams often encounter obstacles when configuring network ingress rules, persistent storage drivers, multi-tenant segmentation, and cluster policies. Engaging specialized Kubernetes Consulting Services equips businesses with production-ready orchestration designs across managed solutions such as EKS, AKS, and GKE.
Additionally, orchestration specialists set up fine-grained service meshes, configure zero-trust network boundaries, and build automated release pipelines. These architectural safeguards prevent configuration drift and deliver secure, enterprise-ready cluster foundations.
How Does DevSecOps Bring Security Into Everyday Development?
Historically, security checks occurred exclusively at the final gate of the delivery lifecycle. Security auditors discovered design vulnerabilities right before launch dates, forcing project delays and sparking contentious arguments between developers and security personnel.
DevSecOps corrects this friction by embedding automated security validation into daily engineering habits. Through targeted DevSecOps Consulting Services, enterprises incorporate automated vulnerability scanners, static analysis utilities, and secrets detection directly into code repositories. Consequently, developers detect and remediate vulnerabilities before code reaches production environments.
Why Is Automation So Important for DevSecOps?
Manual compliance reviews and periodic security audits fail to protect organizations that release code updates multiple times per day. Engineering teams must run programmatic security checks directly inside deployment pipelines to maintain constant verification.
Furthermore, automated policy engines enforce structural compliance rules without human intervention. Integrating static application analysis, container image inspections, and dependency reviews into deployment workflows uncovers software defects instantly, preventing security vulnerabilities and data exposures.
What Is SRE and Why Does Reliability Matter?
Site Reliability Engineering treats operational problems as software development challenges. Instead of managing infrastructure through manual operational intervention, SRE teams develop software mechanisms to monitor uptime, balance system traffic, and coordinate automated incident mitigation.
Organizations leveraging SRE Consulting Services establish objective Service Level Indicators, Service Level Objectives, and actionable Error Budgets. These metrics allow engineering leaders to collaborate transparently, using real performance metrics to decide when to release experimental features or reinforce core platform stability.
How Can Better Observability Help Your Engineering Team?
Simple server heartbeat checks provide little actionable context across complex distributed application meshes. When an outage impacts users, engineers require deep system context to uncover the exact failure source instead of merely seeing that an endpoint failed.
- Numeric Metrics: Capture critical system health indicators, including memory utilization, processor load, network throughput, and error rates.
- Aggregated Logs: Centralize structured event outputs across distinct microservices to uncover the root cause of application failures.
- Distributed Traces: Track individual customer requests across multi-tier backend architectures to pinpoint precise latency bottlenecks.
Unifying these telemetry streams into a centralized visibility dashboard allows support personnel to troubleshoot incidents within minutes, drastically slashing service restoration times.
What Is Platform Engineering and Why Are Teams Adopting It?
The rapid growth of cloud-native tooling creates excessive cognitive strain for modern software developers. Engineers must configure infrastructure templates, maintain container manifests, and troubleshoot deployment pipelines alongside their primary product development duties.
Platform Engineering Consulting Services eliminate this cognitive burden by creating customized internal developer platforms. Dedicated platform teams treat internal developers as clients, delivering clear self-service interfaces, automated infrastructure provisioning, and turnkey configuration templates that eliminate operational bottlenecks.
What Are Golden Paths and How Do They Help Developers?
A Golden Path represents a verified, automated workflow that guides developers as they construct and ship new services securely. Rather than forcing engineers to piece together pipeline definitions independently, platform teams provide pre-built project blueprints.
Crucially, Golden Paths encourage voluntary adoption by providing the smoothest route to production. Developers willingly follow these curated workflows because they come pre-configured with security policies, monitoring plugins, and compliant delivery scripts, allowing teams to deliver microservices with minimal friction.
How Can Corporate DevOps Training Strengthen Internal Teams?
Purchasing modern software tooling without educating existing personnel generates technical confusion and deep external vendor dependencies. Structured Corporate DevOps Training courses equip internal teams with practical skills spanning container orchestration, infrastructure automation, and modern cloud patterns.
In addition, tailored training sessions help developers, operations personnel, and testing specialists adopt a common engineering language. As a consequence, staff members collaborate seamlessly, handle complex systems with confidence, and preserve the momentum of modern engineering initiatives.
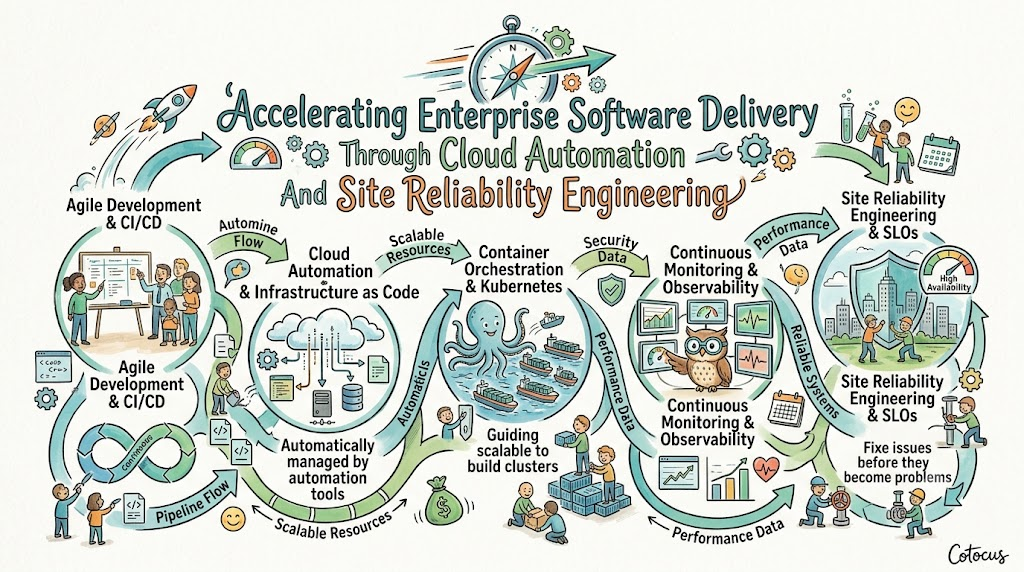
How Do DevOps, Cloud, Kubernetes, and SRE Work Together?
High-velocity engineering environments emerge from the seamless integration of collaborative culture, elastic infrastructure, automated orchestration, and reliability disciplines. When combined, these practices create a resilient, scalable foundation for the modern enterprise.
DevOps establishes communicative deployment workflows, while cloud infrastructure provides dynamic computational power. Meanwhile, Kubernetes automates application scaling, platform engineering abstracts away operational toil, DevSecOps injects automated safety controls, and SRE principles safeguard overall platform availability.
What Problems Can Slow Down a DevOps Transformation?
Many organizations mistakenly treat technical modernization as an off-the-shelf software procurement exercise. However, tools alone cannot repair misaligned incentives or broken cross-team dynamics. When leadership pushes for speed while reprimanding operations for any downtime, structural gridlock inevitably follows.
Furthermore, untangled technical debt and unmapped legacy monoliths routinely derail transformation goals. Teams that attempt to rewrite massive systems in a single sprint quickly stumble into delays. In contrast, successful companies modernize systems iteratively, building institutional trust through continuous, incremental releases.
How Can You Tell Whether Your DevOps Strategy Is Working?
Measuring technical transformation requires clear, quantitative indicators rather than subjective intuition. Technology leaders accurately track organizational progress by evaluating the four standard delivery performance metrics.
| Target Indicator | Emerging Performance Baseline | High-Performing Benchmark | Core Operational Meaning |
|---|---|---|---|
| Deployment Frequency | Monthly or quarterly batches | Continual on-demand production releases | Delivery pipeline velocity |
| Change Lead Time | Multi-month delivery schedules | Less than one single working hour | Time elapsed from commit to production |
| Change Failure Rate | Exceeds 40 percent | Below 15 percent of releases | Frequency of updates causing outages |
| Service Restoration Time | Multiple days or full weeks | Resolved within sixty minutes | Speed of incident mitigation |
Regularly monitoring these indicators exposes development bottlenecks, empowering engineering leadership to apply targeted technical remedies that maximize operational yield.
What Does a Practical DevOps Roadmap Look Like?
A structured engineering transformation follows a practical four-phase progression that secures tangible results at every milestone.
- Phase 1 (Assessment and Foundation): Audit existing delivery workflows, eliminate manual bottlenecks, and centralize version control standards across repositories.
- Phase 2 (Automation and Delivery): Build automated test harnesses, package software into containers, and deploy repeatable integration pipelines.
- Phase 3 (Protection and Visibility): Embed automated code scanners into delivery workflows, unify logging infrastructure, and configure end-to-end tracing.
- Phase 4 (Self-Service and Reliability): Launch self-service developer portals, establish formal Service Level Objectives, and run disciplined incident management routines.
Adhering to this structured roadmap avoids operational surprises, produces measurable wins early, and establishes lasting engineering momentum across all teams.
How Can Cotocus Support Your Modern Engineering Journey?
Scaling complex cloud operations while simultaneously releasing customer features strains existing staff. Organizations needing elastic operational capacity engage our DevOps Outsourcing Services to access experienced cloud architects, Kubernetes engineers, and site reliability specialists who integrate directly into their squads.
Additionally, Cotocus accelerates operational maturity across every phase of technical evolution. From orchestrating CI/CD pipelines and securing cloud environments to establishing custom platform portals and delivering corporate training bootcamps, our specialists ensure your platforms run securely, scale efficiently, and perform reliably.
Frequently Asked Questions About Cotocus
1. What specialized technical services does Cotocus deliver to enterprise clients?
Cotocus supplies comprehensive engineering consulting, managed cloud environments, and operational support. Technical capabilities include CI/CD automation, cloud migrations, Kubernetes design, pipeline security, site reliability engineering, internal developer platforms, and enterprise training.
2. In what ways does external DevOps consulting accelerate software releases?
Consultants examine your existing development pipelines, identify manual handoffs, and assemble resilient continuous delivery workflows. Removing human intervention and adding automated testing suites empowers engineering teams to ship updates rapidly and safely.
3. Which public cloud providers do your migration specialists support?
Engineers support migrations across all primary hyperscale providers, including Amazon Web Services, Google Cloud Platform, and Microsoft Azure. Workloads move smoothly through lift-and-shift patterns, cloud-managed upgrades, or comprehensive microservice refactoring.
4. How do managed operational services protect internal development velocity?
Managed operations assume full ownership of server patching, 24/7 telemetry monitoring, infrastructure updates, and live production incidents. Consequently, internal software engineers focus on building product functionality without handling infrastructure administration.
5. Why should our organization transition application workloads into Kubernetes?
Kubernetes automates application scheduling, dynamic container scaling, health checks, and rolling production updates. This orchestration ensures distributed microservices maintain complete availability during unpredictable traffic spikes.
6. At what point should our engineers introduce DevSecOps into the pipeline?
Teams should introduce automated security scans immediately to intercept configuration vulnerabilities early. Integrating static and dependency testing into deployment pipelines allows developers to patch defects before pushing code into production.
7. Why does Site Reliability Engineering deliver superior results over standard sysadmin support?
Site Reliability Engineering treats IT operations as an engineering discipline driven by automated code rather than manual interventions. Setting objective Service Level Objectives and Error Budgets allows teams to balance rapid software innovation with guaranteed system uptime.
8. How does an Internal Developer Platform reduce engineering cognitive load?
Internal Developer Platforms supply engineers with self-service access to pre-configured infrastructure, automated build pipelines, and approved deployment environments. This self-service model eliminates administrative tickets and helps developers ship features autonomously.
9. In what scenarios should an enterprise utilize technical outsourcing services?
Outsourcing helps enterprises access experienced cloud, platform, and reliability engineers immediately. This operational approach expands delivery capacity rapidly while avoiding prolonged recruitment pipelines and costly employee onboarding periods.
10. What formats are available for corporate technical upskilling workshops?
Corporate education offerings include interactive, hands-on masterclasses tailored to current business architectures. Curriculum modules cover containerization, cloud architectures, pipeline automation, shift-left security practices, and reliable platform operations.
Final Thoughts
Enduring technical excellence stems from cultivating disciplined operational practices supported by automated pipelines, modern cloud infrastructure, and proactive reliability systems. Organizations that invest in workflow standardization, shift-left security automation, and self-service developer platforms build sustainable competitive advantages. Embracing modern DevOps, cloud orchestration, and site reliability principles equips your software teams to innovate quickly, scale predictably, and maintain rock-solid production availability.